Category: Industrial Safety & Monitoring

  • OSHA Awards $10.2 Million in Workplace Safety Training Grants to 67 Organizations

    OSHA Awards $10.2 Million in Workplace Safety Training Grants to 67 Organizations

    The U.S. Department of Labor’s Occupational Safety and Health Administration awarded approximately $10.2 million in Susan Harwood Training Grants to 67 organizations nationwide, the agency announced October 1, 2026, to fund hazard-recognition and prevention training for workers and employers.

    Focus on High-Risk Small Businesses

    The grants, distributed through OSHA’s long-running Susan Harwood Training Grant Program, are intended to support instructor-led training and the development of classroom-ready educational materials on hazard awareness, prevention and controls. OSHA said the funding places particular emphasis on small businesses operating in industries with high rates of injury, illness and fatality, and that roughly a dozen of the awards are specifically earmarked for fall-protection training aimed at residential and commercial construction workers in states including Florida, Pennsylvania and Texas.

    Program’s Origins

    The program is named for Dr. Susan Harwood, who spent 17 years at OSHA developing safety guidance covering benzene, formaldehyde, bloodborne pathogens and lead exposure in construction, and who authored the agency’s cotton dust standard, credited with virtually eliminating byssinosis among textile workers.

    The awards continue a pattern of OSHA funding non-profit groups, employer associations, labor unions, tribal organizations and colleges to deliver safety training directly to at-risk workforces rather than through enforcement alone. Recipients were not individually detailed in the initial announcement, and the full list of awarded organizations was not independently verified beyond the agency’s release. More industrial safety developments are tracked in the SectechMedia Technology News archive.

    Sources

  • Johnson Controls Fixes Two EasyIO Neo Controller Security Flaws

    Johnson Controls Fixes Two EasyIO Neo Controller Security Flaws

    Johnson Controls has released updates for EasyIO Neo controllers after two security issues were documented in separate coordinated advisories. The vulnerabilities concern exposure of sensitive information and transmission of credentials or session information without adequate encryption.

    What the two advisories cover

    CVE-2026-64892 involves information that can be obtained through physical debugging interfaces. CISA gives it a maximum CVSS v3 base score of 3.5. CVE-2026-64893 addresses cleartext transmission of credentials and session data and carries a maximum CVSS v3 base score of 5.4.

    The affected devices are used in building-control environments, where controller credentials can provide a path into operational functions. CISA says it is not aware of public exploitation targeting either issue. Johnson Controls lists the related product advisories JCI-PSA-2026-20 and JCI-PSA-2026-30 on its security-advisory portal.

    Updates and compensating controls

    The vendor identifies EC version 3.3b64 and CW version 3.3b26 as fixed releases. For the network issue, operators should use HTTPS and disable HTTP where their deployment allows it. Physical access to debugging interfaces should also be restricted, with controller locations monitored as part of the site’s security plan.

    Before updating controllers, building operators should document current logic and configuration, confirm a rollback path and schedule functional testing. Network teams should check that management traffic stays on trusted segments. SectechMedia’s industrial safety and monitoring coverage includes further guidance for operational technology estates.

    Sources

  • ABB PCM600 Flaws Could Enable Privilege Escalation and File Overwrite

    ABB PCM600 Flaws Could Enable Privilege Escalation and File Overwrite

    ABB has addressed two vulnerabilities in PCM600, its protection and control engineering tool. CISA says the flaws could let a local attacker elevate privileges or cause project-archive files to be written outside the intended extraction directory.

    Two different local attack paths

    CVE-2026-15952 concerns permissions around a scheduler component running as LocalSystem. Under the conditions described by the advisory, a local user could exploit that arrangement to gain higher privileges. CVE-2026-15953 is a path-traversal issue in project archive handling that could place files beyond the selected extraction folder.

    CISA lists PCM600 versions through 2.14 as affected and gives the vulnerabilities a maximum CVSS v3 base score of 6.4. The agency says it is not aware of public exploitation. ABB has published product security advisories and provides workaround guidance for affected deployments.

    Why engineering workstations need special care

    PCM600 is used in energy-sector protection and control engineering. An engineering workstation can therefore hold trusted project files and privileged access to operational assets even when it is not directly exposed to the internet. Organizations should apply ABB’s guidance, limit local administrator rights and treat imported project archives as untrusted until validated.

    Before remediation, teams should back up projects and confirm recovery procedures. Afterward, review scheduled tasks, extraction directories and endpoint telemetry for unexpected files or privilege changes. SectechMedia’s energy-security coverage examines the wider operational context for protecting utility and industrial environments.

    Sources

  • Single Malformed Packet Can Crash TDengine Industrial Database Servers

    Single Malformed Packet Can Crash TDengine Industrial Database Servers

    Security researchers have disclosed a pre-authentication vulnerability in TDengine that can allow an unauthenticated attacker to crash the time-series database with a single malformed packet. The issue, tracked as CVE-2026-42542, is relevant to industrial, energy, IoT, building-automation and connected-vehicle environments that rely on continuous telemetry.

    The flaw targets an operational data layer

    Ridge Security says the weakness occurs while the server processes network data before authentication. A specially formed packet can trigger an integer-underflow condition and terminate the database process. Even without data theft or code execution, repeated crashes can disrupt dashboards, alarms, analytics and other services that depend on current time-series data.

    Industrial databases are often treated as internal infrastructure, but remote access paths, flat networks and exposed management services can make them reachable from less trusted zones. Availability loss can also obstruct operators during a separate physical or cyber incident.

    Segmentation and recovery testing matter

    Asset owners should identify TDengine deployments, review vendor remediation guidance and restrict database ports to necessary systems. Monitoring should alert on repeated process termination and abnormal packets, while recovery exercises should verify that dependent applications reconnect safely. SectechMedia covers related controls in its OT and cyber-physical security coverage.

    Sources

  • DAS Event Classification Acceptance Testing and Model Drift Control

    DAS Event Classification Acceptance Testing and Model Drift Control

    Distributed acoustic sensing can monitor long fiber routes, but acceptance should evaluate more than whether the interrogator detects vibration. The system must distinguish agreed event classes, localize them usefully and remain manageable as the environment changes.

    Define event classes and evidence

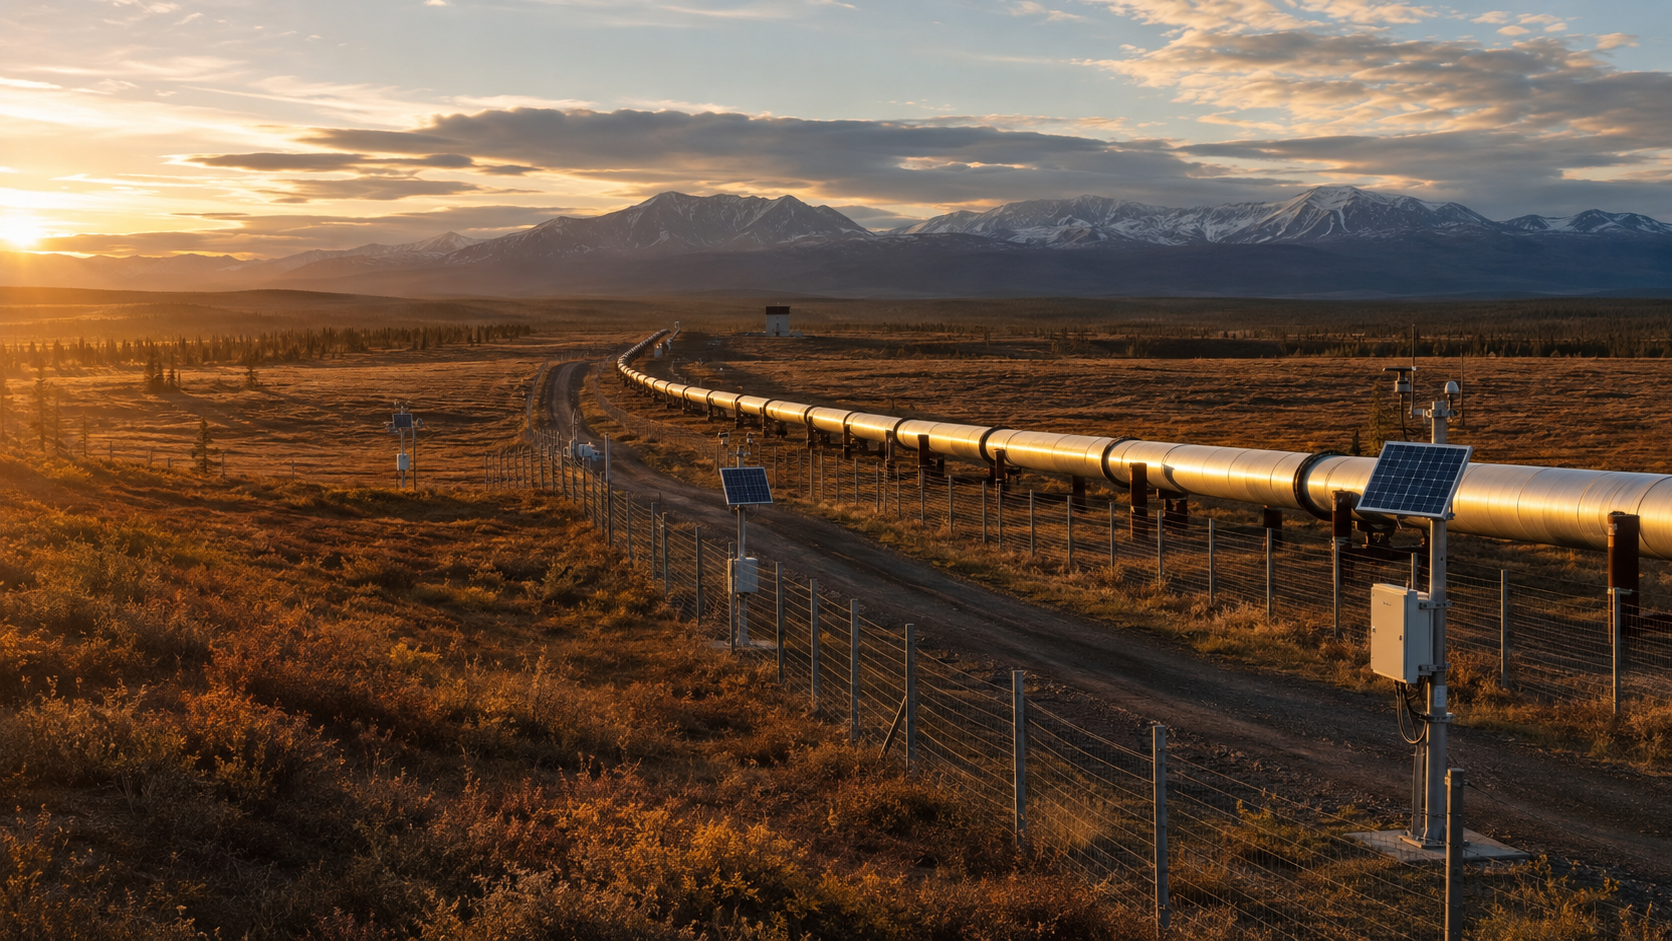
    List the events the system is expected to identify, such as fence disturbance, excavation, vehicle movement or activity near a pipeline. Define each class in operational terms and state which events require an alarm, investigation or record only.

    Agree on test methods, route sections, repetitions and acceptance metrics before testing. Avoid adopting a generic vendor demonstration as the site requirement. Soil, cable coupling, fence construction and background activity strongly affect the signal.

    Build a representative test set

    Run events at different distances from the fiber and at several points along the route. Include strong and weak examples, boundary locations and simultaneous background activity. Record weather, time, operating conditions and the personnel or equipment used.

    Collect nuisance sources such as maintenance work, traffic, animals and weather-driven movement. A classifier that performs well only in quiet conditions has not demonstrated operational readiness.

    Measure detection and classification separately

    Record whether the system detected an event, how it classified it, its reported location and the time to alarm. A detected event with the wrong class may trigger the wrong response; a correctly classified event with poor localization may still waste operator time.

    Review confusion between classes rather than relying on one combined accuracy figure. Confirm how low-confidence results are presented and whether operators can inspect supporting traces.

    Control model and threshold changes

    Back up the accepted configuration, model version and training assumptions. Any retraining or threshold change should be tested against a fixed regression set before deployment. Track changes in nuisance alarms and missed events across seasons.

    This lifecycle control belongs within Fiber Optic Sensing governance. It is especially important after route work, cable repair, vegetation changes or new nearby machinery.

    Monitor for drift

    Compare live alarm distributions with the acceptance baseline and investigate sustained changes by location, class or confidence. Keep operator feedback structured; ad hoc relabeling can contaminate future training data. Periodically repeat controlled field events and document whether performance remains within the approved envelope. Where it does not, treat retraining as a controlled engineering change with rollback and independent review.

    Define operational review and rollback

    Specify who may approve model or threshold changes and which evidence is required. Preserve the previous model and configuration so the system can be restored if nuisance alarms or missed detections increase after deployment.

    Review field feedback by route section, event class and confidence rather than as one sitewide total. Confirm that operators receive understandable classifications and supporting traces. A lifecycle report should distinguish sensor health, detection performance, classification performance and response workflow.

    Reference sources

  • Thermal Camera Reference Validation and Measurement Drift Testing

    Thermal Camera Reference Validation and Measurement Drift Testing

    A thermal camera can produce a stable image while its reported temperatures gradually move away from the accepted reference. Commissioning and maintenance should therefore test the complete measurement chain rather than judging image quality alone.

    Define the intended measurement task

    Start by documenting whether the camera is used for relative hot-spot detection, threshold alarms or traceable temperature measurement. These are different tasks. A system intended only to highlight warmer objects may not need the same reference procedure as a process-protection alarm.

    Record the camera model, lens, mounting distance, field of view, firmware, measurement range and alarm rules. Preserve the approved emissivity, reflected-temperature and atmospheric settings. A changed parameter can shift readings without any physical change at the target.

    Use a controlled reference

    Place an appropriate temperature reference in the scene and allow it to stabilize. The reference should cover the temperatures important to the application and occupy enough pixels for a repeatable measurement. Compare the camera result with the reference value at several points rather than relying on one threshold.

    Where formal traceability is required, use calibrated equipment and retain its certificate, uncertainty and due date. A convenient warm object is useful for a functional check but is not a calibration reference.

    Control environmental variables

    Measure ambient temperature, viewing angle, distance and any window or protective enclosure between the camera and target. Dust, moisture, solar loading and reflections can alter apparent temperature. Verify that automatic gain or image-enhancement settings do not affect the radiometric measurement channel.

    Repeat tests after the enclosure reaches operating temperature and under representative day and night conditions. For outdoor systems, include seasonal extremes and check whether background reflections move the alarm point.

    Trend drift and alarm performance

    Record reference error, image location, alarm response time and pass limits. Trend results across maintenance visits so gradual drift is visible before it causes missed or nuisance alarms. When error exceeds the approved tolerance, investigate settings and environment before applying software offsets.

    After service or replacement, repeat the full alarm sequence, event recording and control-room notification. Thermal-camera assurance belongs within broader Video Surveillance & Imaging governance, with separate records for image quality and temperature performance.

    Keep the test reproducible

    Store reference placement drawings, camera screenshots, raw readings, weather observations and instrument identifiers. State whether the result is a field verification or a formal calibration. This distinction prevents future teams from assigning more confidence to the measurement than the evidence supports.

    Classify and close deviations

    Separate configuration errors, reference uncertainty, environmental effects and suspected sensor drift. Assign corrective work to the responsible owner and repeat the same reference points after intervention. Do not close a deviation only because an alarm threshold was widened.

    Review recurring errors across similar cameras and locations. A common offset may indicate a shared enclosure, firmware or commissioning issue. Keep acceptance limits tied to the operational hazard so maintenance teams know when a camera can remain in service and when it must be removed for laboratory evaluation.

    Reference sources

  • Honeywell OT Benchmark Finds Asset Visibility Lagging Security Confidence

    Honeywell OT Benchmark Finds Asset Visibility Lagging Security Confidence

    A Honeywell benchmark survey has found a gap between industrial organizations’ confidence in their operational-technology cybersecurity programs and the asset records and monitoring controls they report having in place. Security Today published the findings on September 28.

    Complete inventories remain uncommon

    The report surveyed more than 600 leaders responsible for cybersecurity risk, compliance or operations across energy, oil and gas, healthcare, maritime and manufacturing. Security Today reported that 88% described their programs as mature, while 21% said they maintained complete OT asset records.

    Only one-third of surveyed organizations reported complete OT integration with centralized security operations centers. Continuous oversight of connected cameras, sensors and other IoT devices was less common, illustrating how physical and operational technology can remain outside enterprise monitoring.

    Confidence should be tested against evidence

    Self-assessed maturity is useful only when it is supported by current inventories, documented ownership, network visibility and tested incident procedures. Unknown engineering workstations, unmanaged remote links and unsupported controllers can undermine segmentation and response even when governance frameworks appear complete.

    Operators can begin by reconciling discovery data with approved asset registers, assigning a business owner to every device and recording software, support and recovery dependencies. The benchmark reinforces a recurring theme in Cyber-Physical Security: resilience depends on knowing which systems exist, how they communicate and which operational consequences follow when they fail.

    Sources

  • FBI and CISA Warn Critical Infrastructure Operators About ICS Integrator Access

    FBI and CISA Warn Critical Infrastructure Operators About ICS Integrator Access

    The FBI and the Cybersecurity and Infrastructure Security Agency issued guidance on September 23 about cybersecurity risks created when third-party industrial control system integrators receive access to critical-infrastructure environments. The agencies urged operators to treat integrator connections as governed, monitored access paths rather than permanent trusted links.

    A provider breach exposed customer information

    According to the guidance summarized by Security Today, a 2025 breach of a US industrial automation provider affected an organization serving power and transportation customers. Foreign actors searched the provider network for customer and supervisory control and data acquisition material, then placed hundreds of items into compressed archives.

    The episode illustrates how a compromise at one engineering or support company can create visibility into multiple operators. Drawings, device information and customer SCADA data can help attackers understand industrial environments even when they have not yet reached an operational network.

    Access should be limited and observable

    The agencies recommended limiting each integrator to the access required for its work, recording remote sessions and documenting supplied technology. Contracts should define cybersecurity obligations, while operators should maintain offline copies of software needed to run equipment and prepare for a provider becoming unavailable.

    Organizations should also review dormant accounts, shared credentials, remote-access gateways and support pathways after projects end. These controls align supplier governance with technical segmentation and operational resilience. The warning is especially relevant to SectechMedia readers responsible for Industrial Safety & Monitoring, where maintenance access can cross the boundary between business systems and essential processes.

    Sources

  • NIST Quantum Sensors Improve Nuclear Material Monitoring Accuracy

    NIST Quantum Sensors Improve Nuclear Material Monitoring Accuracy

    NIST researchers and international partners have used ultrasensitive quantum sensors to measure X-ray emissions from uranium, plutonium and neptunium with substantially improved precision. The measurements can help analysts separate those X-rays from overlapping gamma-ray signals used to identify and account for nuclear material.

    Transition-edge sensors resolve overlapping signals

    The work used arrays of transition-edge sensors, superconducting devices operated just above absolute zero. An incoming photon produces a measurable change in resistance, allowing the detector to determine its energy with high resolution. NIST reports that the new measurements reduced uncertainty by between one-third and one-eighth compared with earlier values.

    More accurate X-ray data allows monitoring systems to subtract background interference and estimate isotope ratios more precisely. Those ratios are important for nuclear safeguards because they help distinguish material composition and enrichment.

    Deployment still requires specialized infrastructure

    The sensors need cryogenic cooling and are not handheld instruments. NIST says arrays can operate where sufficient power and refrigeration are available, while samples can also be sent to equipped laboratories. The technology may shorten measurement delays at nuclear facilities, but operational adoption requires calibration, chain-of-custody controls and validated procedures. SectechMedia follows related systems in its industrial monitoring coverage.

    Sources

  • Security System MTTR Metrics and Critical Spare Parts Planning

    Security System MTTR Metrics and Critical Spare Parts Planning

    Security availability depends on more than failure rate. A device that fails rarely can still create unacceptable exposure if repair takes weeks because the part, configuration or specialist is unavailable. Mean time to repair and critical-spares planning connect maintenance records with operational risk.

    Define repair time consistently

    Choose when the MTTR clock starts and stops. Useful stages include detection, ticket creation, diagnosis, parts arrival, physical repair, configuration and verified return to service. One overall average can hide delays caused by logistics or approval.

    Separate active repair time from waiting time while retaining both. A technician may replace a camera in an hour after the correct model arrives, but a ten-day procurement delay still affects service availability.

    Rank assets by operational consequence

    Classify devices and components according to the function they support. A recorder power supply, access controller, fire-network card or perimeter processor may affect many downstream points. Spares should follow consequence and lead time, not simply the number of devices installed.

    Include software licenses, certificates, configuration backups, mounting hardware and compatible power supplies. A shelf containing the main device is not a complete recovery capability if activation keys or approved firmware are unavailable.

    Use failure history without overfitting

    Review faults by model, age, environment and cause. Repeated failures may justify additional stock, but they may also indicate heat, power quality, water ingress or poor installation. Buying more of the same component does not correct a systemic cause.

    Track parts consumed, returned and found defective. Rotate stock where batteries, seals or other components age in storage. Verify that replacement models remain interoperable with the deployed platform before older parts become unavailable.

    Test the recovery process

    Run controlled replacement exercises for selected critical assets. Confirm access to backups, credentials, firmware, tools and test equipment. Measure restoration through functional read-back rather than ending the clock when hardware powers on.

    Review MTTR trends with service-level targets and temporary mitigations. A bypassed zone or borrowed camera may reduce immediate risk but should not close the permanent repair ticket. Maintenance metrics support broader Industrial Safety & Monitoring resilience when they expose where staffing, logistics or configuration control delays recovery.

    Govern inventory and obsolescence

    Assign ownership for minimum stock, storage conditions, firmware compatibility and replenishment. Review manufacturer end-of-sale and end-of-support notices so a critical spare does not depend on an unavailable model or unsupported software branch.

    Quarterly inventory checks should compare physical stock with maintenance records and planned projects. Reserve critical parts for restoration rather than allowing project work to consume them without replacement. The resulting evidence connects spare holdings to actual risk, repair history and tested recovery capability.

    Record substitutions and compatibility decisions. An emergency replacement should not become an undocumented permanent configuration that future maintenance teams cannot reproduce.

    Reference sources